Stumbling over Microsoft’s Video Conferencing Dataset (VCD) I asked Claude to take on a video codec engineer’s favorite hot take: compare video codecs. It did a fairly good writeup using the tooling provided by libWebRTC. One of the most surprising results was that background blur makes H.264 a lot more effective. Other than that, the results were not surprising, but it is interesting how little guidance Claude needed to produce the writeup.
Which video codec is the best?
“Which video codec is the best” has always been a question that was hotly debated. Back in 2013 there was the question of which codec was mandatory to implement with two camps, one favoring H.264 and another favoring VP8. webrtcHacks covered much of the debate back in the day. In the end, both H.264 and VP8 ended up being mandatory to implement. In the decade that followed new codecs such as VP9, AV1 and HEVC made it into WebRTC.
Newer codecs deliver either higher quality at the same bitrate or the same quality at a lower bitrate. Comparisons are made and codecs are picked, sometimes interesting talks are given at conferences like Meta’s rtc@scale. Doing these experiments has always been a lot of effort and executing often means running experiments and updating spreadsheets. Unsurprisingly this task has gotten easier in 2026 so I decided to have Claude do a comparison of VP8, VP9, H.264 and AV1 on the VCD.
This dataset consists of 160 “talking head” videos so should be fairly representative for WebRTC use-cases. We focus on the 120 of those recorded in landscape for desktop use and ignore the 40 recorded on mobile phones. So the original prompt I used inside my libWebRTC checkout was along the lines of
Can you grab the dataset from https://github.com/microsoft/VCD and use it to make a comparison of VP8, VP9, H.264 and AV1 at 320×180,640×360, 1280×720 and 1920×1080 at different bitrates (150kbps, 500kbps, 2500kbps and 4000kbps respectively for the resolutions) and compare PSNR? Make a plan first and tell me how much effort it is
These resolutions and bitrates are often used in simulcast and the bitrates were picked from libWebRTC’s simulcast settings for VP8.
Claude came up with a plan using libWebRTC’s internal tooling for doing the comparison, wrote scripts to extract the data and even made charts. This used to take a week or two which is why we see this either rarely or with a much smaller scope such as Gustavo Garcia’s 2021 comparison.
The main comparison metric is PSNR (peak signal-to-noise ratio). Statistics for this recently shipped in Chromium-based browsers. The quantization parameter (QP), which has long been exposed in statistics, is useful for tuning a codec implementation but, as expected, is not comparable across codecs because each codec defines it differently.
Looking at the results,
- PSNR of VP9 and AV1 is noticeably higher than for VP8 and H.264 which makes sense, this is a jump in the codec generation. The gap between VP9 and AV1 is surprisingly small but a better comparison would be at their respective operating points.
- H.264 is beating VP8 at higher resolutions, while using less CPU.
- H.264 is really good at talking heads with blurred background, performing significantly better than VP8 and close to VP9 and AV1. It is pretty obvious that background blur should improve video coding efficiency but the increase in H.264 PSNR is surprisingly high.
Note that these are pure encoder/decoder-based results that do not take the network and its effect such as variable bitrates into account. Your LLM should be able to reproduce the results from the notes attached which might be a good starting point for experimentation.
Other than that,
- the methodology writeup is solid. Note that apart from scripts the tooling was already part of libWebRTC which means someone at Google has been doing this for a while, e.g. to decide the numbers in the simulcast table. But since this happened at Google nobody saw the presentation they surely had for it.
- VMAF had to be added but that is not surprising, it is not commonly used for video conferencing. PSNR and VMAF show the same direction. PSNR has the advantage of being available in browser stats.
- The operating point is a bit unfair with the VP8 simulcast bitrates but one has to make a comparison. Interestingly, H.264 still “won” against VP8. That it has not actually won in WebRTC is determined by factors this comparison does not take into account: features like simulcast integration, temporal scalability, suitability for screensharing or rate control.
- QP is useful for comparing how a codec operates but cannot be compared across codecs. That is why I wanted PSNR in the WebRTC statistics.
Overall, this is a solid result; the VCD dataset makes this a realistic exercise. Not much more than that, the decision on which video codec to invest in has largely been settled in AV1’s favor. Investigations like this show the direction but actually making codec decisions requires more direct comparisons at different bitrates and at the end of the day A/B experiments in the field.
And this benchmarking exercise led to two low-langing fruits:
- a 1-2% win in the libvpx VP8 denoiser which made it more consistent with the VP9 and libaom approach (who can say no?)
- another 1-2% in OpenH264’S encoder which used MMX instructions to do small memsets to 0 – the generic memset did better on modern CPUs
Small improvements but as LLMs like to say “it compounds”.
{“author”: “Philipp Hancke“}
What Claude wrote
Everything below here was written by Claude. Note that it may read better in the print version.
VP8, H.264, VP9 and AV1 on Microsoft’s video-conferencing dataset
1,920 encode–decode runs across 120 clips, measured with WebRTC’s own codec test harness at the simulcast ladder’s target bitrates, scored with both PSNR and VMAF. AV1 and VP9 land 3.5 dB above VP8 at 1080p; the gap between them is a tenth of the gap either has over the incumbent, and the two metrics disagree about which of them wins.
- Dataset Microsoft VCD, 120 landscape clips
- Runs 1,920 quality + 1,920 VMAF + 1,920 timing
- Harness video_codec_perf_tests
- Metrics PSNR-Y and VMAF, 300 frames @ 30 fps
How this was measured
The dataset
The Video Conferencing Dataset is Microsoft’s open corpus for exactly this kind of work: 160 clips of a person on camera, 1080p at 30 fps, 10 seconds each, spanning a deliberate range of camera qualities and spatial and temporal complexity. It is split into four scenarios of 40 clips, and that split is what makes it useful here, because conferencing codecs meet very different content depending on what the user has switched on.
- th
- Talking head. Plain webcam capture, speaker gesturing or reading. The closest thing to an unmodified call.
- th-ob
- Opaque background. The background is replaced, as Teams and Meet do by default in many deployments. Synthetic, flat and highly compressible.
- th-bb
- Background blur. Heavy blur applied behind the speaker, which removes most high-frequency detail from the majority of the frame.
- th-m
- Mobile. Recorded on phones, and portrait at 1080×1920. Excluded here, since the landscape bitrate ladder does not apply to it.
That leaves 120 landscape clips, 40 per scenario. Clips are served from a public Azure blob under the Community Data License Agreement (Permissive 2.0), in both raw YUV and MP4. The MP4s were used and decoded to raw I420 per clip. Because the decoded MP4 is the common reference for every codec, source compression does not bias one codec against another. It does, however, mean the experiment measures performance on this distribution rather than on pristine camera output.
The libWebRTC tooling
No standalone encoder CLI was involved. Everything ran through WebRTC’s own codec test harness, video_codec_perf_tests, defined in modules/video_coding/BUILD.gn. Its VideoCodecTest.DISABLED_EncodeDecode case is a flag-driven single-run entry point, disabled by default so it does not run in CI, which encodes a clip, decodes it back and reports per-frame statistics:
|
1 2 3 4 5 6 7 8 |
out/Default/video_codec_perf_tests --gtest_filter=VideoCodecTest.DISABLED_EncodeDecode --gtest_also_run_disabled_tests --input_path=clip.yuv --input_width=1920 --input_height=1080 --input_framerate_fps=30 --encoder=libvpx-vp8 --decoder=libvpx-vp8 --width=640 --height=360 --bitrate_kbps=500 --num_frames=300 --num_cores=2 |
This matters because the harness instantiates the real CreateBuiltinVideoEncoderFactory and CreateBuiltinVideoDecoderFactory, so every run exercises the same encoder wrappers, the same rate-control glue and the same libyuv scaling path that a live PeerConnection would use. Downscaling from the 1080p source to each rung happens inside the harness rather than in FFmpeg, and PSNR is computed against that scaled source, which is what keeps the four resolutions self-consistent. The codec pairs are the software stack WebRTC ships: libvpx for VP8 and VP9, OpenH264 encoding with the FFmpeg decoder for H.264, and libaom encoding with dav1d decoding for AV1.
Each run prints psnr_y_db, psnr_u_db, psnr_v_db, qp, encoded_bitrate_kbps, bitrate_mismatch_pct, encode_time_us and decode_time_us, aggregated over the 300 frames, and those lines are parsed straight from stdout. Adding --write_csv also drops a per-frame CSV next to the run, one row per encoded frame carrying timestamp_rtp, per-frame PSNR, QP, frame size and the keyframe flag.
Adding VMAF
PSNR is computed inside the harness, but VMAF is not, so the second metric needs the pixels. --dump_encoder_input and --dump_decoder_output write the frames the encoder was handed and the frames that came back out of the decoder, as y4m, the uncompressed frame-sequence container FFmpeg and libvmaf both read. That is the same pair CalcPsnr consumes, so both metrics score byte-identical data and no separate encode is involved:
|
1 2 3 4 5 |
--write_csv --dump_encoder_input --dump_decoder_output --test_name=vmaf/${clip}_${codec}_${width} vmaf -r ..._enc_input-s0.y4m -d ..._dec_output-s0.y4m -m version=vmaf_v0.6.1:name=v061 -m version=vmaf_v0.6.1neg:name=neg --json -o out.json |
Two details are load-bearing. Encoders drop frames under rate control, so the decoder output can be shorter than the encoder input, and comparing the two sequentially would misalign everything after the first drop. The harness itself is immune because it pairs by RTP timestamp, but the y4m dumps carry no timestamps, so the decoded-frame index list is recovered from the per-frame CSV and the reference is subset to match. And libvmaf silently returns 0.0 when a .y4m and a raw .yuv are mixed in one call rather than reporting an error, which is why the upscaled comparison feeds raw on both sides.
The operating points
Bitrates come from WebRTC itself rather than from round numbers. The target_bitrate column of kSimulcastFormatsVP8 in video/config/simulcast.cc is what a sender would actually allocate to a layer at each resolution, so those are the points measured: 150, 500, 2500 and 4000 kbps for 180p, 360p, 720p and 1080p. All four codecs were held to the VP8 ladder so the comparison is like-for-like, even though AV1 and VP9 would in practice draw from kSimulcastFormatsVP9, which the same file defines just below it. Those are meaningfully lower: 142, 420, 1524 and 3367 kbps for the same four rungs, so WebRTC already assumes VP9 needs 16% less bitrate at 1080p and 39% less at 720p to do the same job. Holding VP9 and AV1 to the VP8 numbers therefore hands them more bitrate than a real sender would, and the quality gaps below should be read as the ceiling of what the newer codecs buy, not as what a deployed ladder would deliver. One point per resolution means this is a fixed-operating-point comparison, not a rate-distortion sweep, and so it yields no BD-rate: the Bjøntegaard delta, the single number that says how much bitrate one codec saves over another at matched quality, is computed from a curve through several rates per codec, and there is one rate per codec here.
Every run is L1T1 — one spatial layer, one temporal layer, so no simulcast and no SVC, just a plain single stream — with no additional temporal layers, a single keyframe at frame 0, frame dropping left on, and two cores, over all 300 frames of each clip. That comes to 1,920 encode-decode runs for the four-codec comparison, plus a further 1,920 for the single-pass timing measurement that the encode-cost chart draws on.
PSNR-Y by resolution
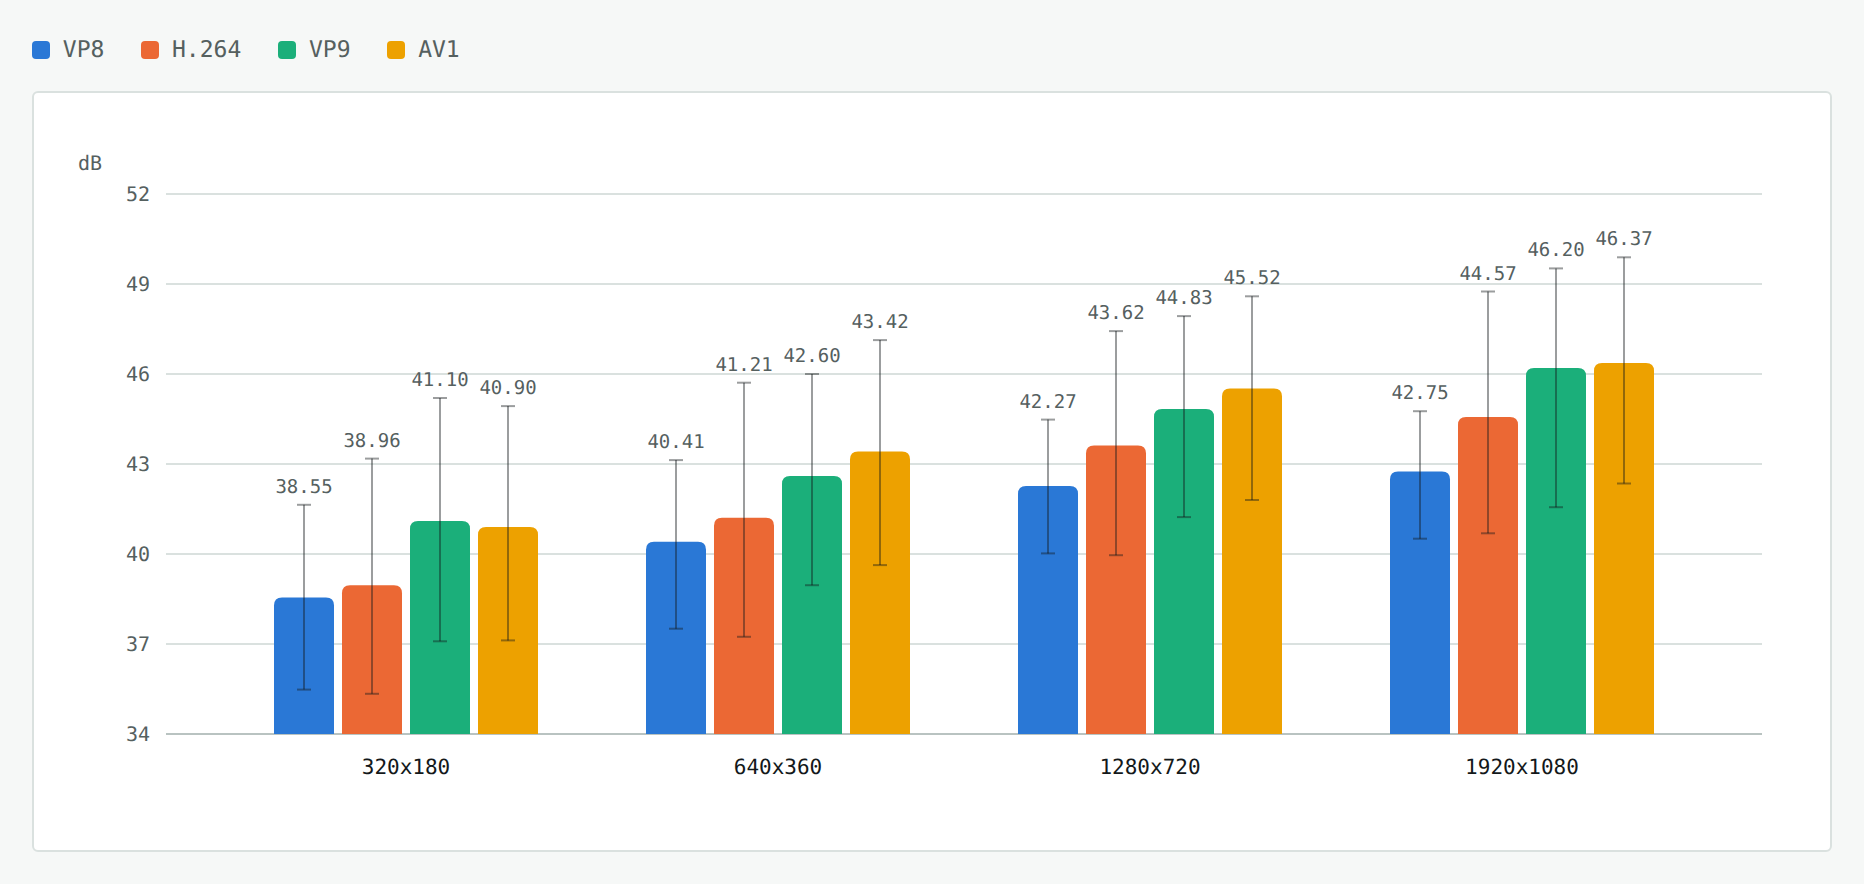
Why a subset. On the easiest clips, the ones with a replaced or blurred background, AV1 and OpenH264 sometimes reach their best-quality setting and simply cannot use all the bitrate they were given, delivering as little as 60% of it. Averaging those in would compare codecs at different rates. It affected 116 of the 1,920 runs, all of them AV1 or OpenH264; VP8 and VP9 always spent their budget. The full table reports both views, with a per-resolution count in its “saturated” column.
Reading the ranking
The ordering starts with VP8 < H.264 at every rung, while VP9 and AV1 take the top two spots and trade the lead. The intervals are uneven. Moving off VP8 to VP9 or AV1 is worth 2.2–3.6 dB, and to OpenH264 only 0.4–1.8 dB; choosing AV1 over VP9 is worth between −0.20 and +0.82 dB depending on resolution. At 180p VP9 is actually ahead of AV1 by 0.20 dB, and AV1’s lead only becomes clear at 360p and above, peaking at +0.82 dB at 360p before narrowing again to +0.17 dB at 1080p.
H.264 here is OpenH264, which is what WebRTC ships rather than what the format can do. It is the weakest of the three modern options on quality but by far the cheapest to run.
The ranking depends on what is behind the speaker
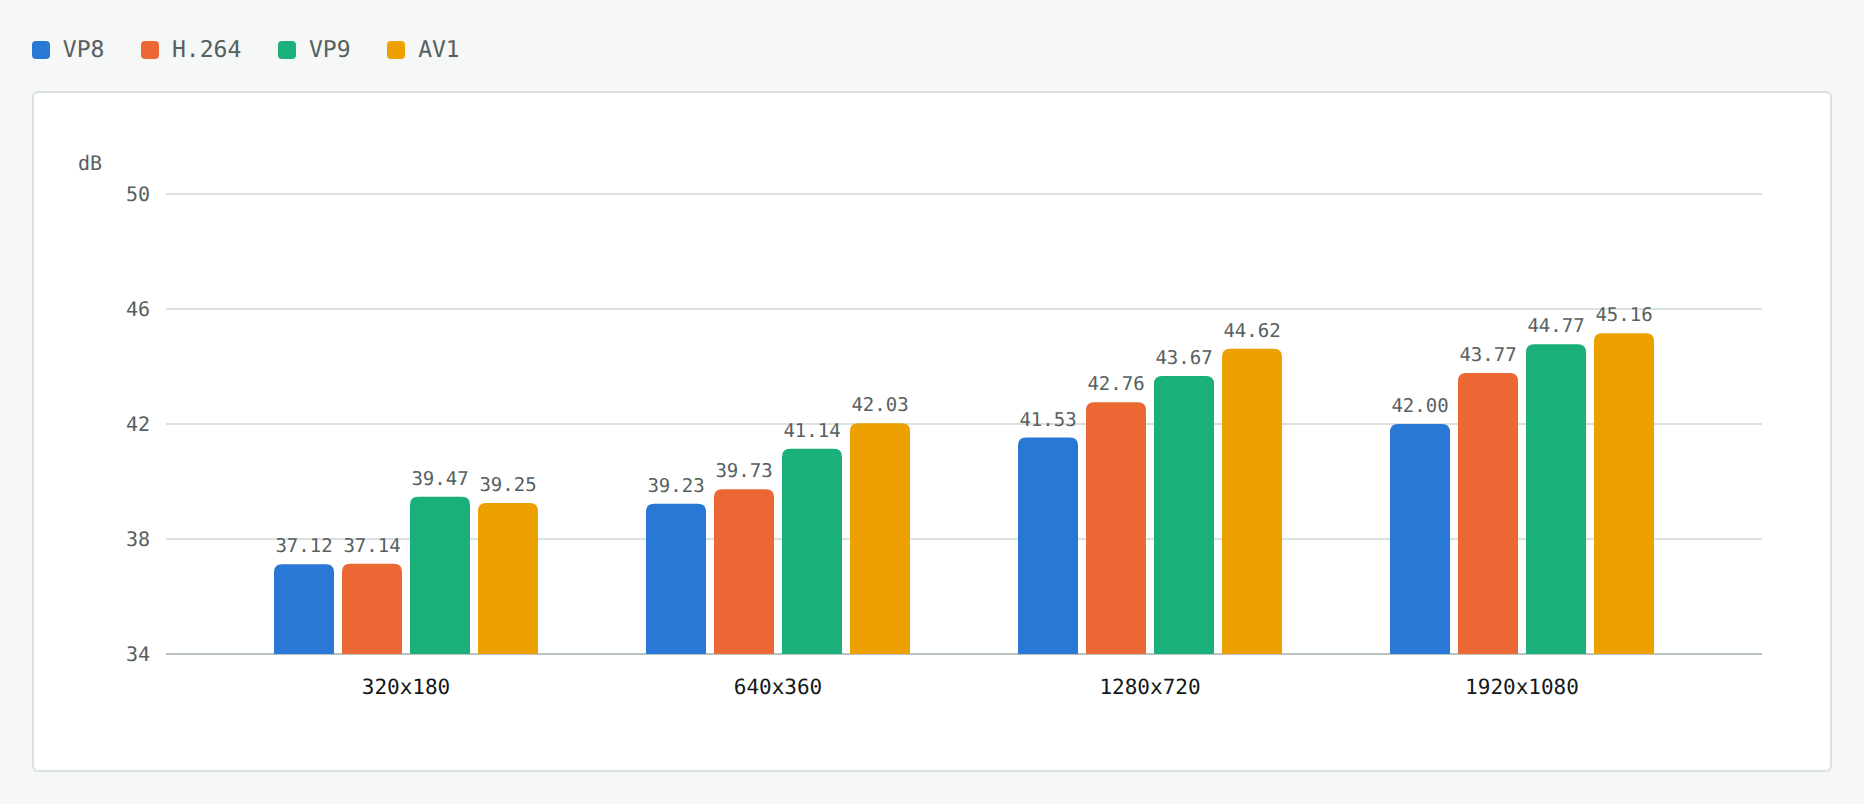
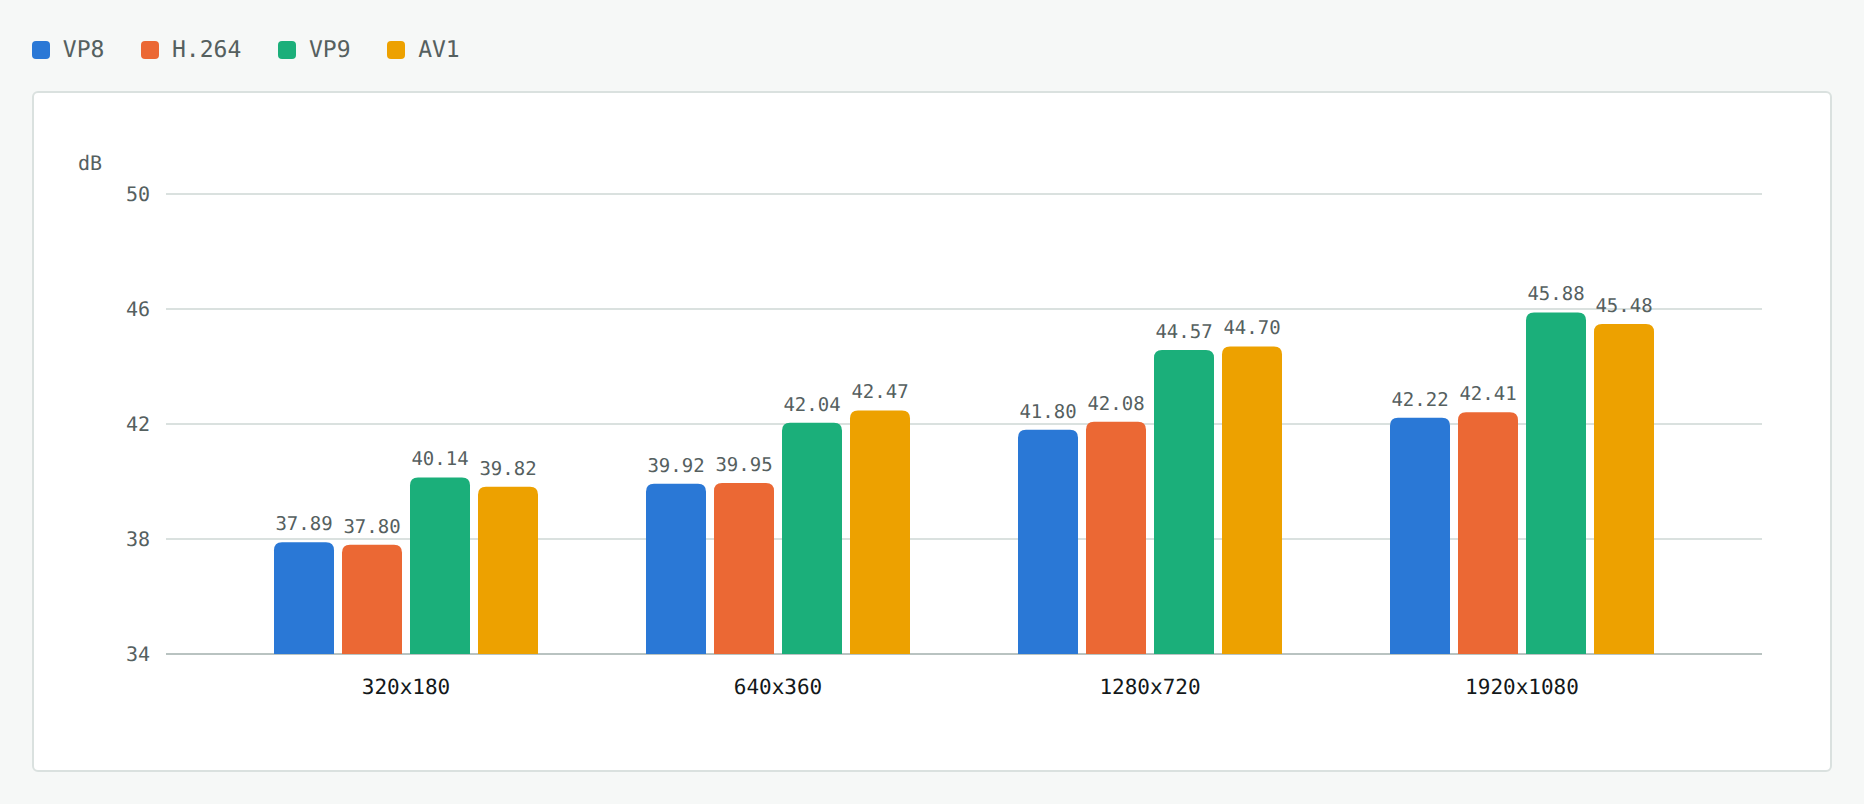
This is the part of the dataset that earns its keep. Splitting the same 120 clips by scenario turns a single ordering into three different ones, and the effect is not small: for OpenH264 the spread between the easiest and hardest scenario at 1080p is 5.58 dB, larger than the entire 3.62 dB gap between VP8 and AV1 in the pooled result. Which background mode your users have switched on matters more, for that encoder, than which codec you picked. A corpus of plain webcam footage would have shown none of this.
All three panels below are PSNR-Y in dB, one per scenario, on the same axis so they can be read against each other. The table beneath them is at 1080p. What VMAF makes of the same split is covered further down.
Talking head · PSNR-Y (dB)
Opaque background · PSNR-Y (dB)
Blurred background · PSNR-Y (dB)
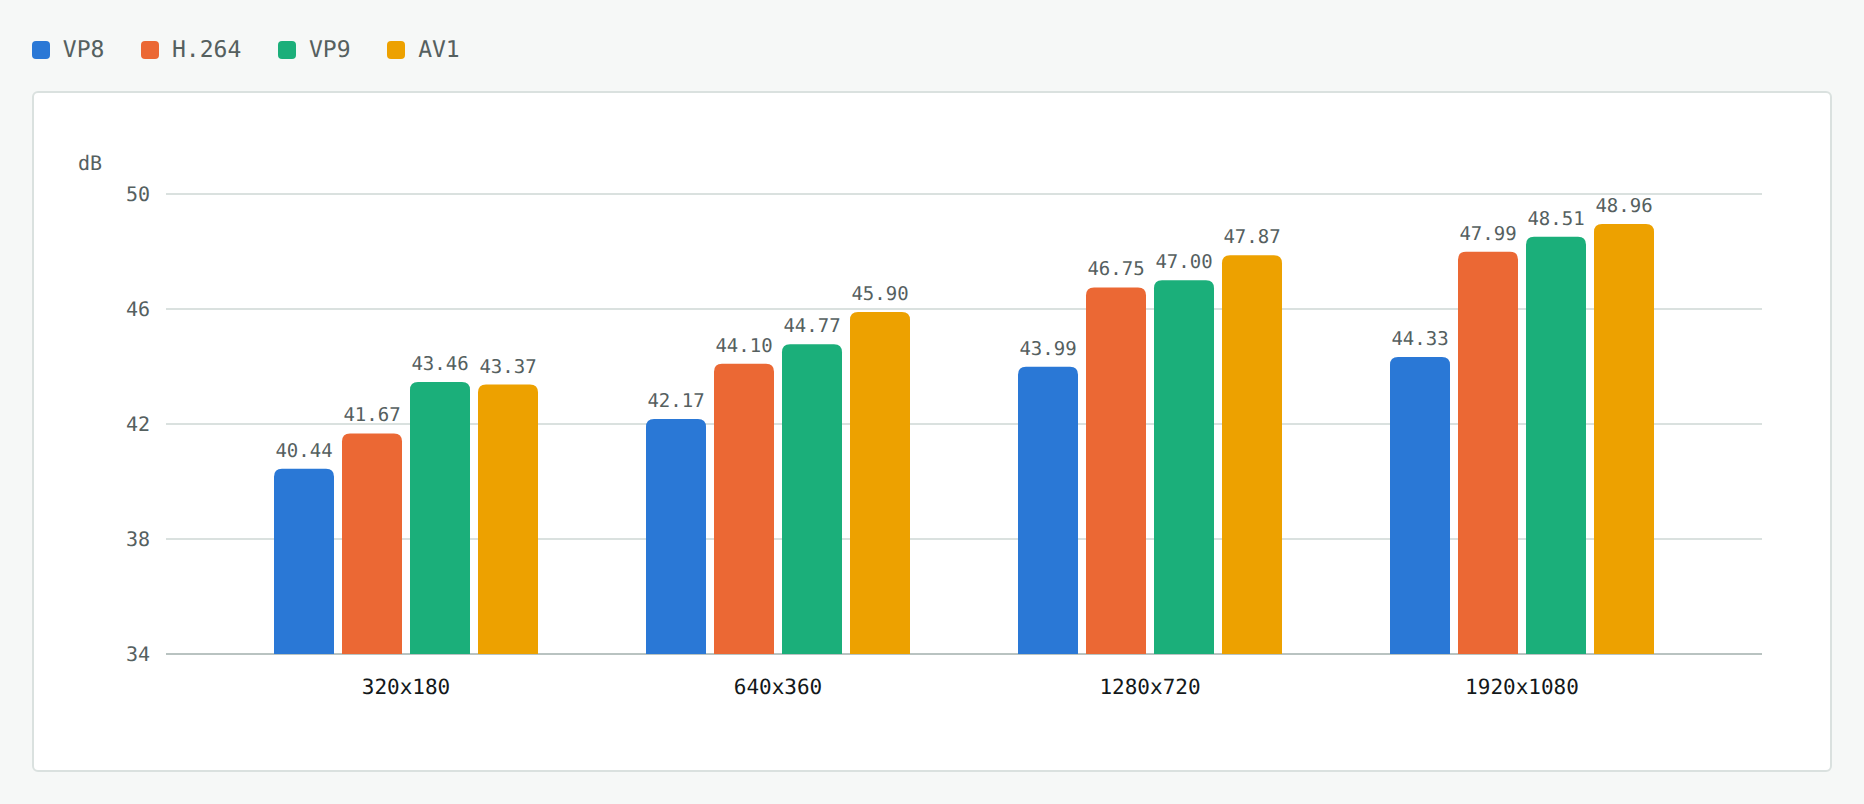
| Codec @1080p | Talking head | Opaque background | Blurred background | Spread | vs VP8, worst | vs VP8, best |
|---|---|---|---|---|---|---|
| VP8 | 42.00 | 42.22 | 44.33 | 2.33 dB | — | — |
| H.264 | 43.77 | 42.41 | 47.99 | 5.58 dB | +0.19 | +3.66 |
| VP9 | 44.77 | 45.88 | 48.51 | 3.74 dB | +2.77 | +4.18 |
| AV1 | 45.16 | 45.48 | 48.96 | 3.80 dB | +3.16 | +4.63 |
Three things fall out of this. OpenH264 is content-dependent to a degree the others are not: on a replaced background it gains 0.19 dB over VP8, which is nothing, but under background blur it gains 3.66 dB and lands within half a dB of VP9. The AV1-versus-VP9 answer flips: AV1 leads on plain talking head and on blur, but on opaque replaced backgrounds VP9 is ahead by 0.40 dB. And the synthetic backgrounds are not simply easier, they are differently hard: blur is easier for every codec, while a flat replaced background is the scenario that separates the codecs most, suggesting that the modern codecs exploit its large uniform regions more effectively than OpenH264.
PSNR and VMAF, side by side
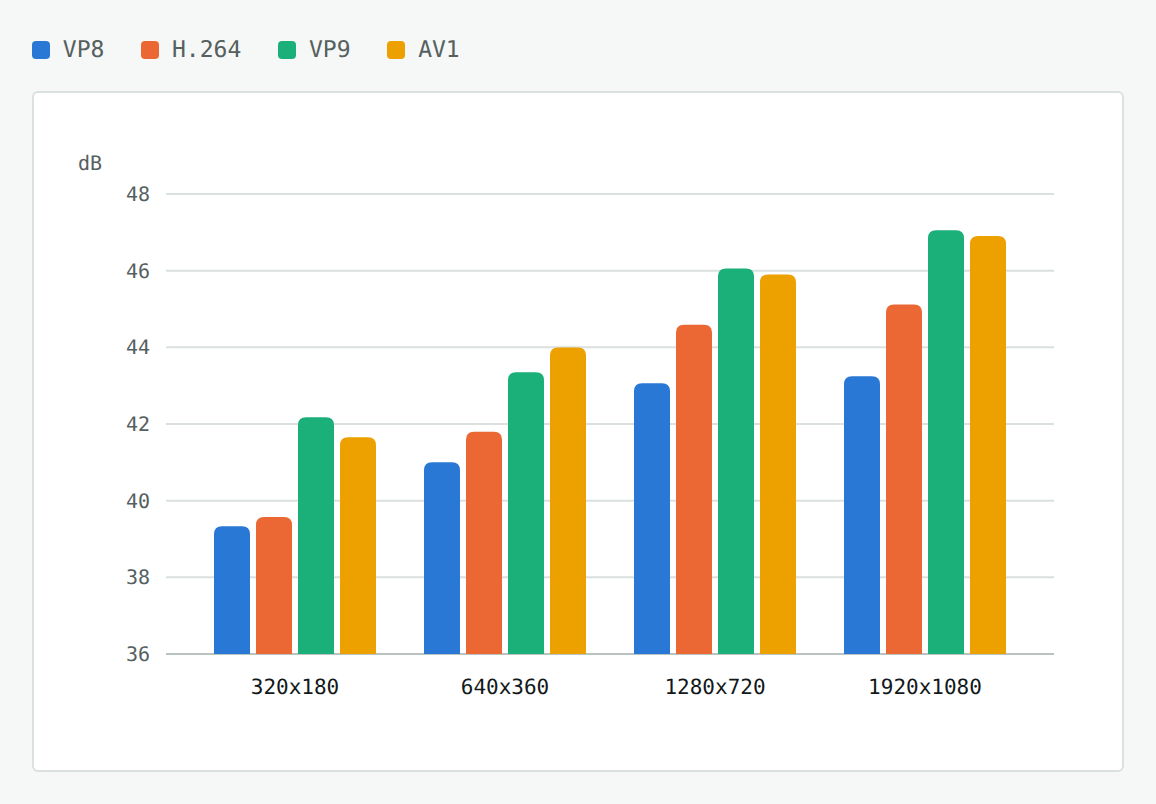
Each run in the VMAF pass was scored with both VMAF, Netflix’s perceptual metric, and PSNR on exactly the same pixels: the frames the harness fed the encoder against the frames its decoder returned. Nothing was re-encoded between the two scores, so the panels below are two readings of the same 1,920 VMAF-pass runs rather than separate experiments. Both use all 120 clips, which is why the left panel sits a little above the rate-matched chart further up.
Why carry both. VMAF is intended to track perceived picture quality better than PSNR, but the v0.6.1 model used here was trained for entertainment viewing rather than video conferencing. PSNR is the one you can actually get here: it is cheap enough to compute per frame inside the encoder loop, it is what video_codec_perf_tests reports, and it is now in getStats() in the browser, so it is the only one of the two you can read off a live call. In this workflow, VMAF needs both sequences and a second pass. Running them together checks whether the cheap number tells the same story: where they agree, PSNR is a useful proxy, and where they disagree, the metric choice is part of the result.
PSNR-Y · dB
VMAF · at encode resolution
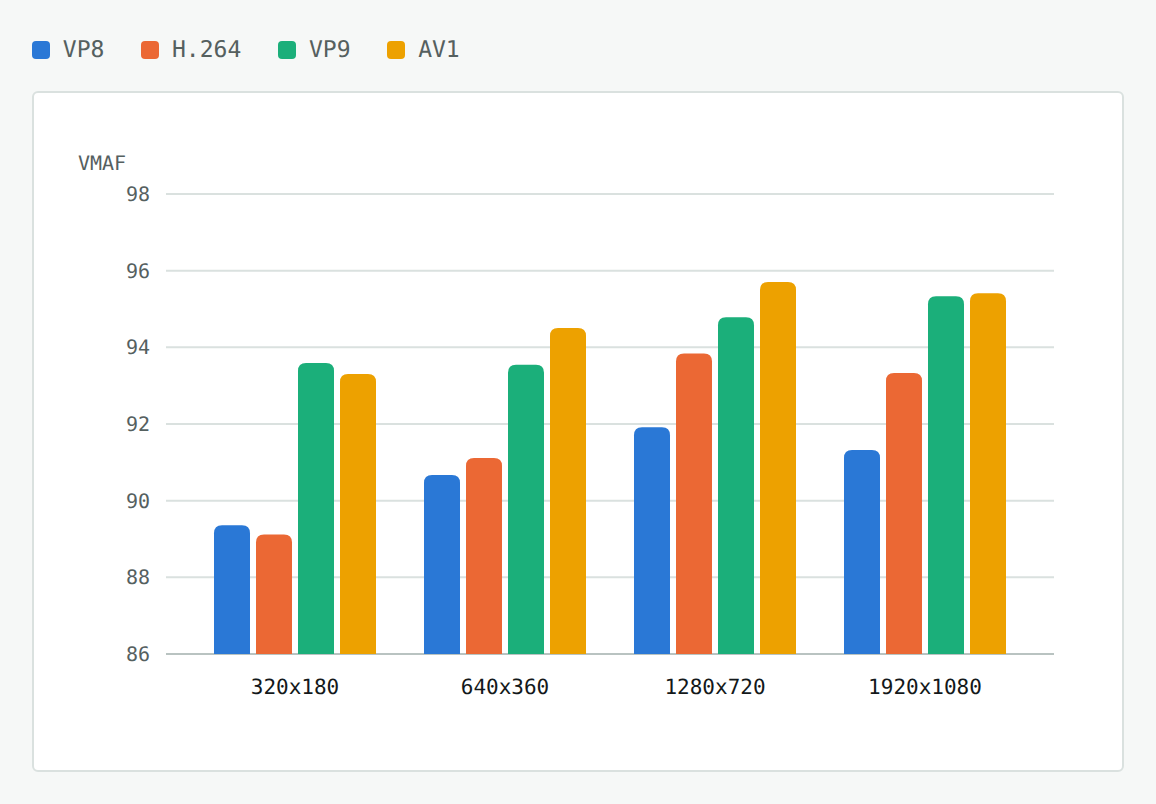
The two axes are deliberately not shared: decibels and VMAF points are different quantities and putting them on one scale would invent a relationship that does not exist. What is comparable is the shape, and it mostly agrees. The broad separation survives: VP8 trails H.264, while VP9 and AV1 remain well ahead. The top two trade places depending on resolution and metric.
| Codec | Δ PSNR-Y vs VP8 | Δ VMAF vs VP8 | Clips won, PSNR | Clips won, VMAF | Metrics agree |
|---|---|---|---|---|---|
| 320×180 · target 150 kbps · all 120 clips | |||||
| H.264 | +0.24 dB | -0.24 | 66/120 | 47/120 | 82% |
| VP9 | +2.84 dB | +4.23 | 120/120 | 120/120 | 100% |
| AV1 | +2.32 dB | +3.95 | 120/120 | 120/120 | 100% |
| 640×360 · target 500 kbps · all 120 clips | |||||
| H.264 | +0.79 dB | +0.44 | 83/120 | 69/120 | 75% |
| VP9 | +2.35 dB | +2.88 | 120/120 | 120/120 | 100% |
| AV1 | +2.99 dB | +3.84 | 120/120 | 120/120 | 100% |
| 1280×720 · target 2500 kbps · all 120 clips | |||||
| H.264 | +1.53 dB | +1.92 | 103/120 | 102/120 | 88% |
| VP9 | +3.00 dB | +2.87 | 120/120 | 120/120 | 100% |
| AV1 | +2.84 dB | +3.79 | 120/120 | 120/120 | 100% |
| 1920×1080 · target 4000 kbps · all 120 clips | |||||
| H.264 | +1.87 dB | +2.01 | 96/120 | 96/120 | 77% |
| VP9 | +3.81 dB | +4.01 | 120/120 | 120/120 | 100% |
| AV1 | +3.66 dB | +4.08 | 120/120 | 120/120 | 100% |
Two rankings actually flip, and the table shows them differently. At 180p the sign changes: PSNR puts OpenH264 ahead of VP8 and VMAF puts it behind, marked in amber. At 720p and 1080p the order changes without any sign changing, so read the two bold cells in each block instead: PSNR’s leader is VP9 and VMAF’s is AV1. Both flips involve differences small enough that the metric choice determines the ranking.
But only for the close calls. VP9 and AV1 beat VP8 on 120 of 120 clips under both metrics at every rung: perfect unanimity, nothing to argue about. OpenH264 against VP8 is the one contested comparison, and there the two metrics pick the same per-clip winner only 75–88% of the time. That is not VMAF being erratic. It is two metrics resolving a genuinely close race differently, which is the useful warning: a sub-decibel PSNR difference is not a result.
Where the OpenH264 disagreement comes from
Splitting that contested comparison by scenario resolves it. The pooled 180p flip is not a property of OpenH264, it is the average of two scenarios where VMAF punishes it and one where VMAF rewards it more than PSNR does.
| H.264 minus VP8 | Δ PSNR-Y | Δ VMAF | Δ VMAF, 1080p screen* | Clips won, PSNR | Clips won, VMAF | Metrics agree |
|---|---|---|---|---|---|---|
| Talking head · 40 clips | ||||||
| 320×180 | -0.05 dB | -1.12 | -0.47 | 16/40 | 15/40 | 92% |
| 640×360 | +0.45 dB | -0.46 | -0.17 | 27/40 | 18/40 | 78% |
| 1280×720 | +1.30 dB | +1.55 | +1.61 | 39/40 | 33/40 | 85% |
| 1920×1080 | +1.76 dB | +1.82 | +1.82 | 39/40 | 29/40 | 75% |
| Opaque background · 40 clips | ||||||
| 320×180 | -0.46 dB | -1.39 | -0.97 | 12/40 | 2/40 | 75% |
| 640×360 | -0.12 dB | -0.69 | -0.95 | 16/40 | 17/40 | 62% |
| 1280×720 | +0.20 dB | +0.44 | +0.18 | 24/40 | 30/40 | 80% |
| 1920×1080 | +0.05 dB | +0.47 | +0.47 | 17/40 | 28/40 | 58% |
| Blurred background · 40 clips | ||||||
| 320×180 | +1.23 dB | +1.79 | +2.74 | 38/40 | 30/40 | 80% |
| 640×360 | +2.05 dB | +2.48 | +3.99 | 40/40 | 34/40 | 85% |
| 1280×720 | +3.09 dB | +3.78 | +4.26 | 40/40 | 39/40 | 98% |
| 1920×1080 | +3.80 dB | +3.74 | +3.74 | 40/40 | 39/40 | 98% |
* The fourth column scores the same encodes the way a viewer meets them: decoded, then scaled back up to a 1920×1080 window with a bicubic filter and compared against the original 1080p source, which is Netflix’s convention for comparing encodes made at different resolutions. At the 1080p rung it is the same computation as the second column.
On blurred background the two metrics simply agree, and VMAF is the more generous of the two. OpenH264 beats VP8 on every rung under both, and VMAF makes the gap larger at three of the four: +1.79 against +1.23 dB at 180p, +2.48 against +2.05 at 360p, +3.78 against +3.09 at 720p, converging only at 1080p where PSNR says +3.80 and VMAF +3.74. Per-clip agreement runs 80% to 98%, the highest anywhere in this dataset. Scored the way a viewer receives it, the advantage is bigger again, +2.74 at 180p against a PSNR reading of +1.23. Whatever OpenH264 is doing with a heavily blurred background, it is not an artifact of PSNR’s preference for smooth error.
The reverse holds on the other two scenarios. On plain talking head and on an opaque replaced background, VMAF is consistently harsher on OpenH264 than PSNR is: at 180p it goes from −0.05 dB in PSNR to −1.12 VMAF points on talking head and from −0.46 dB to −1.39 VMAF points on opaque, and at 1080p on opaque PSNR calls it a tie at +0.05 dB while VMAF gives it +0.47 points on only 28 of 40 clips. That is where the pooled flip is manufactured. One more thing falls out: on blurred background at 720p, VMAF puts OpenH264 ahead of VP9, 95.07 against 94.66, while PSNR has VP9 ahead 48.23 to 47.88. The cheapest encoder in the set wins a rung outright on the perceptual metric.
The vmaf_v0.6.1neg model, which removes the enhancement-gain term that rewards sharpening, was recorded alongside. It widens every gap rather than closing it: pooled over all runs VP9 goes from +3.50 to +3.89 and AV1 from +3.91 to +4.40 against VP8. Whatever the modern codecs are winning on here, it is not a filtering artifact that VMAF over-credits.
QP does not travel between codecs
Quantizer is the number people reach for when they want a cheap quality signal, because it is in every encoder’s output and needs no reference frame. Across codecs it is meaningless, and this dataset shows why. Each codec reports QP on its own scale, and the scales are not merely differently sized, they are differently shaped: a quantizer index is an index into that codec’s own step-size table, not a quantity of distortion.
Which QP is this? The value recorded here is EncodedImage::qp_, which is the same field that accumulates into qpSum in getStats(), so these are the numbers an application actually sees. Each encoder fills it from a different place:
- VP8
VP8E_GET_LAST_QUANTIZER, 0–127 (libvpx_vp8_encoder.cc:1328, where the local is candidly namedqp_128). The 0–63 variantVP8E_GET_LAST_QUANTIZER_64is also called, but only to feed the temporal-layer controller, notqp_.- VP9
VP8E_GET_LAST_QUANTIZERagain, reusing the VP8 control id, but on VP9 that returns 0–255 (libvpx_vp9_encoder.cc:1816).- AV1
AOME_GET_LAST_QUANTIZER, 0–255 (libaom_av1_encoder.cc:1151).- H.264
- Not an encoder control at all: the slice QP is parsed back out of the bitstream by
H264BitstreamParser::GetLastSliceQp(), 0–51 (h264_encoder_impl.cc:632).
So the same struct field carries four different quantities, one of them recovered by re-parsing the encoder’s own output. This is not merely a reporting quirk, it is webrtc-stats issue 799: WebCodecs specifies 0–63 for AV1, while Chromium reports the libaom qindex, so getStats() returns AV1 QP values above 63 and hardware encoders may well pick a different convention again. The tree is not even internally consistent on this point. The newer encoder behind LibaomAv1EncoderFactory uses AOME_GET_LAST_QUANTIZER_64 and reports 0–63 (libaom_av1_encoder_v2.cc:788), and the speed controller in the old encoder divides by 4 with the comment “Use [0, 63] range instead of [0, 255]” (libaom_av1_encoder.cc:128). Two AV1 QP conventions are live in the same checkout.
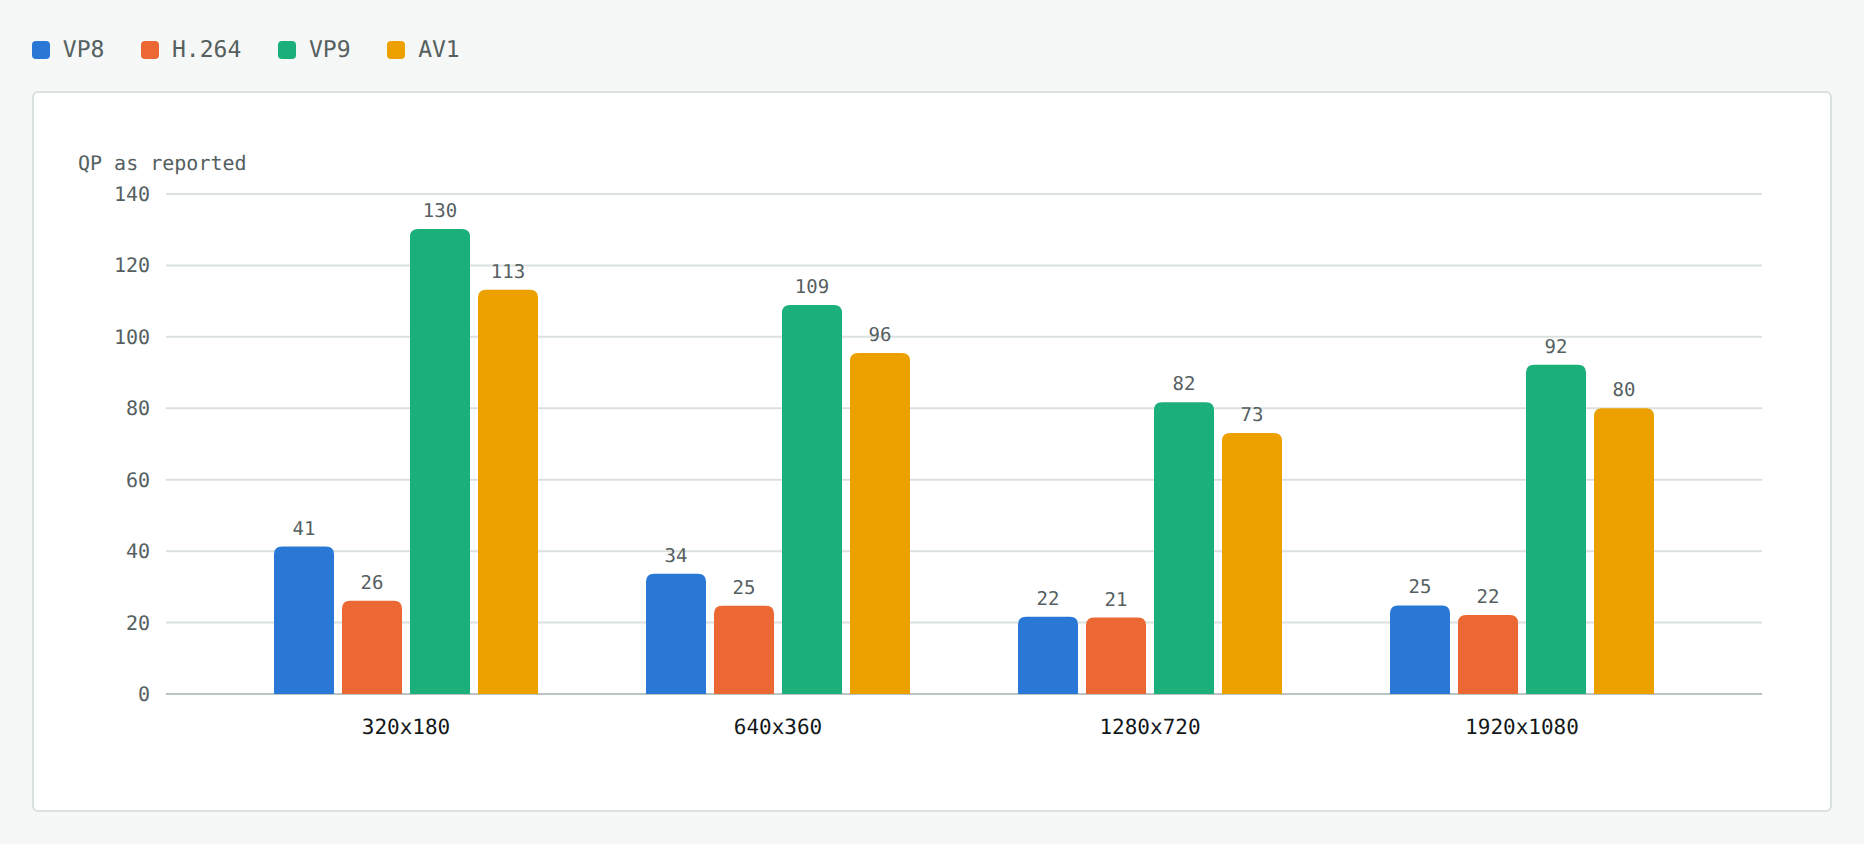
| Codec | QP scale | QualityScaler low / high | Mean QP @1080p | % of own scale | PSNR-Y @1080p | QP rank | PSNR rank |
|---|---|---|---|---|---|---|---|
| VP8 | 0–127 | 29 / 95 | 24.8 | 19.5% | 42.75 | 2 | 4 |
| H.264 | 0–51 | 24 / 37 | 22.1 | 43.4% | 44.57 | 1 | 3 |
| VP9 | 0–255 | 149 / 205 | 92.2 | 36.2% | 46.20 | 4 | 2 |
| AV1 | 0–255 | 145 / 205 | 80.0 | 31.4% | 46.37 | 3 | 1 |
Ranks are 1 = best, so a metric that carried across codecs would put the same codec first in both columns. Nothing does. The thresholds in the third column are WebRTC’s own: the QualityScaler decides when to drop resolution from QP, and it needs a completely different pair of numbers per codec to do it, which is the clearest in-tree statement that these values do not share a scale.
Normalising does not rescue it. At 1080p, VP8 sits at 20% of its scale, AV1 at 31%, VP9 at 36% and H.264 at 43%. That ordering is still not the quality ordering, which runs VP8, H.264, VP9, AV1 from worst to best. The honest use of QP is within one codec, as a relative signal over time, which is exactly what the QualityScaler uses it for. Comparing a VP9 QP against an H.264 QP, or reading a single QP as an absolute quality level, produces conclusions the reference measurement contradicts.
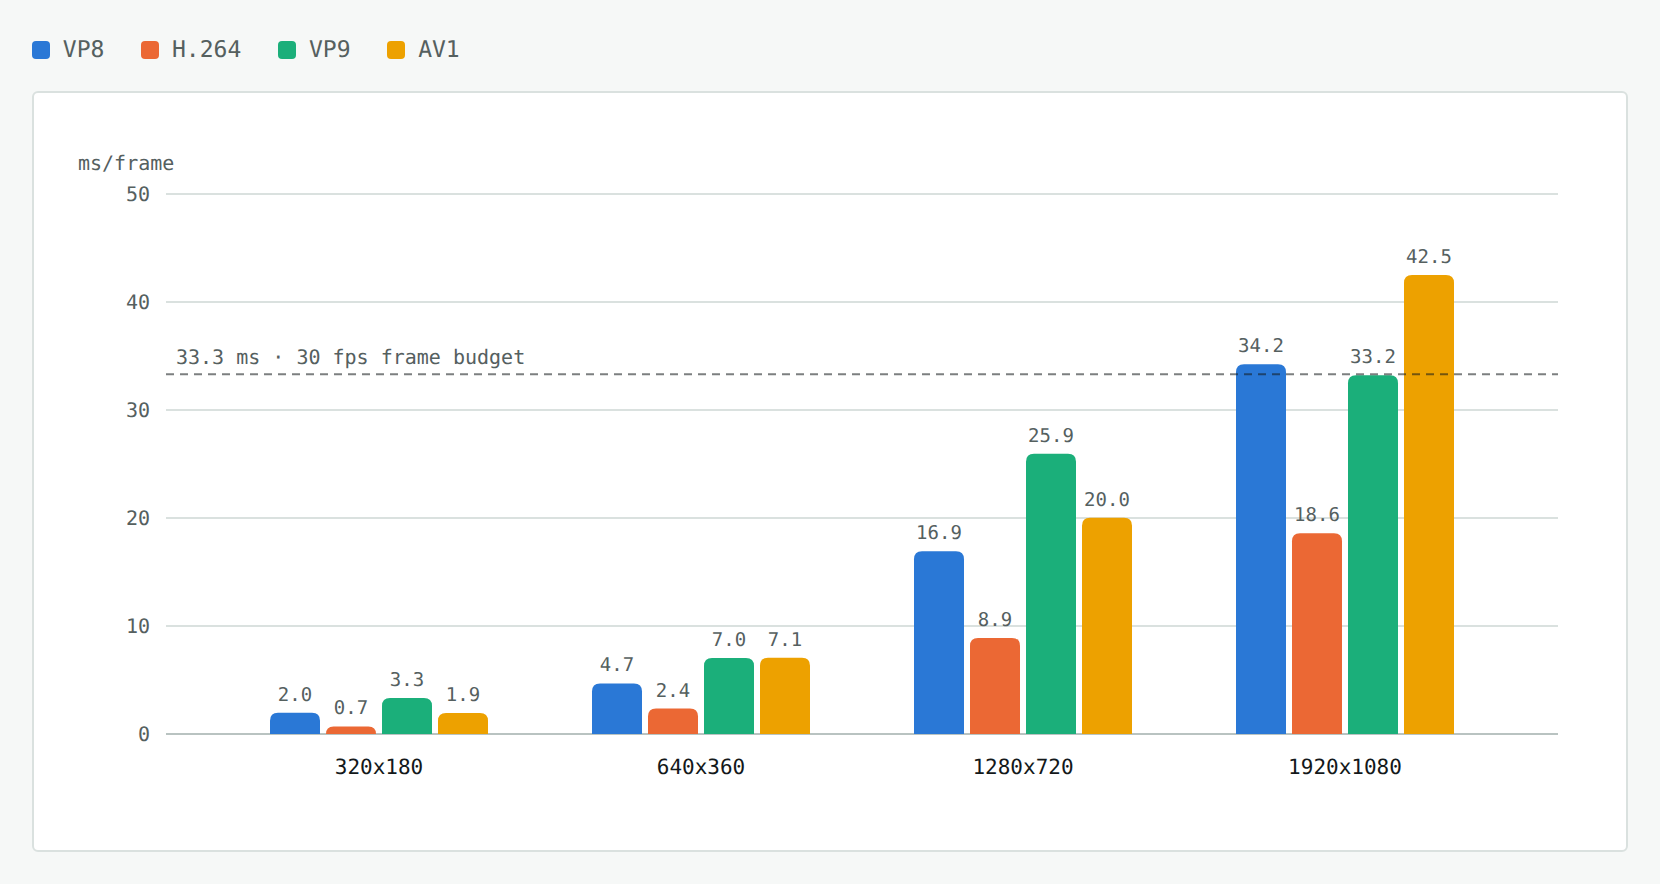
Encode cost per frame
Full results
| Codec | PSNR-Y rate-matched | PSNR-Y all clips | Delivered | vs target | Saturated | Encode ms/f | Decode ms/f |
|---|---|---|---|---|---|---|---|
| 320×180 · target 150 kbps · 93 rate-matched clips | |||||||
| VP8 | 38.55 | 39.33 | 148k | -1.3% | · | 1.96 | 0.78 |
| H.264 | 38.96 | 39.57 | 138k | -8.0% | 16 | 0.70 | 0.30 |
| VP9 | 41.10 | 42.17 | 151k | +0.7% | · | 3.33 | 0.55 |
| AV1 | 40.90 | 41.65 | 146k | -2.7% | 10 | 1.94 | 0.76 |
| 640×360 · target 500 kbps · 96 rate-matched clips | |||||||
| VP8 | 40.41 | 41.00 | 494k | -1.2% | · | 4.68 | 1.48 |
| H.264 | 41.21 | 41.80 | 473k | -5.4% | 9 | 2.35 | 0.85 |
| VP9 | 42.60 | 43.35 | 499k | -0.2% | · | 7.03 | 1.84 |
| AV1 | 43.42 | 43.99 | 474k | -5.2% | 14 | 7.06 | 2.13 |
| 1280×720 · target 2500 kbps · 71 rate-matched clips | |||||||
| VP8 | 42.27 | 43.06 | 2473k | -1.1% | · | 16.91 | 6.07 |
| H.264 | 43.62 | 44.59 | 2328k | -6.9% | 14 | 8.90 | 3.40 |
| VP9 | 44.83 | 46.06 | 2491k | -0.4% | · | 25.95 | 7.66 |
| AV1 | 45.52 | 46.46 | 2172k | -13.1% | 29 | 20.03 | 6.00 |
| 1920×1080 · target 4000 kbps · 93 rate-matched clips | |||||||
| VP8 | 42.75 | 43.25 | 3955k | -1.1% | · | 34.23 | 11.54 |
| H.264 | 44.57 | 45.12 | 3834k | -4.2% | 6 | 18.58 | 6.87 |
| VP9 | 46.20 | 47.06 | 4005k | +0.1% | · | 33.21 | 12.33 |
| AV1 | 46.37 | 46.91 | 3721k | -7.0% | 18 | 42.49 | 10.98 |
Bold marks the best codec in each column within a resolution block. “Saturated” counts clips undershooting target by more than 20%. PSNR and bitrate come from the 1,920-run quality pass; the two timing columns come from the separate single-pass timing run, so they match the encode-cost chart above rather than being spliced from a different set of machine conditions.
On the “vs target” column: setting the saturated runs aside, VP9 lands essentially exactly on target (mean −0.01%, sd 0.61) and VP8 carries a consistent 1% offset with an equally tight spread. AV1 is unbiased but noisier (sd 2.30), and OpenH264 is the one outlier, both low and wide (mean −2.06%, sd 2.52). It is a small effect against the several-dB differences above, and it is OpenH264 specifically, not H.264.
The saturated runs set aside above are a hard QP clamp, not a controller decision. OpenH264 forces iMinQp to at least GOM_MIN_QP_MODE = 12 and iMaxQp to MAX_LOW_BR_QP = 42 whenever the caller leaves them unset (rc.h:70, applied at encoder_ext.cpp:383), and WebRTC’s h264_encoder_impl.cc never sets either. 44 of the 480 OpenH264 runs come back with a mean QP below 14, spread evenly across all four rungs, and they miss target by a mean of 31.8% and a worst case of 65.6%. Re-running the worst of them with --write_csv, 275 of its 300 frames sit exactly at QP 12 and the median frame is 120 bytes against a 625-byte budget: the encoder has run out of quality to buy and simply declines the rest of the bitrate. That is a clamp, and it accounts for 37 of the 45 runs more than 20% short.
Clear of the clamp the controller is still the loosest of the four. Taking only runs with a mean QP of 20 or more, OpenH264 lands at −1.88% with sd 2.74 and 13.8% of runs more than 5% short, worst case −15.3%. VP8 is −1.13% with sd 0.61 and VP9 ±0.11% with sd 0.55, and neither misses by more than 5% on a single run out of 480. So the answer is both: a clamp on easy content, and a genuinely wider controller everywhere else.
Method and limits
- Source. The VCD MP4 distribution, roughly 11.5 Mbps H.264 at 1080p30, decoded to raw I420 per clip. The decoded MP4 is the common reference, so source compression does not favor one codec; however, the results may not generalize to pristine camera output.
- Scope. The 120 landscape clips only: 40 each of talking head, opaque background and blurred background. The 40 portrait mobile clips were excluded because the landscape bitrate ladder does not apply to them.
- Configuration. L1T1, with no additional temporal layers, one keyframe at frame 0, frame dropping enabled, two cores per run. 300 frames per clip.
- One operating point per resolution. No rate sweep, so no BD-rate. These are fixed-bitrate comparisons at the points WebRTC’s simulcast ladder would actually pick.
- AV1 does not reproduce exactly. The identical AV1 configuration has now been re-run twice, and neither replication was bit-exact: the timing pass differed on 148 of 480 runs (median 0.06 dB, worst 0.98 dB) and the VMAF pass on 176 of 480 (median 0.26 dB, worst 1.62 dB), both concentrated at 720p and 1080p. That is libaom’s multi-threaded encode at two cores, not measurement error. It does not move the aggregates, AV1’s 1080p mean shifted by 0.006 dB between the first two passes, but per-clip AV1 figures should be read as approximate. VP8, H.264 and VP9 reproduced exactly in both replications, 0 of 480 runs differing each time, which is what isolates the effect to libaom.
- VMAF is out of domain. The
vmaf_v0.6.1model is trained for 1080p HDTV viewing on Netflix catalog content, not video conferencing. It is a standard perceptual metric and is useful here for relative comparisons, but its absolute values on this corpus should not be treated as calibrated opinion scores. - Neither metric charges for a dropped frame. Rate control skips frames, and a skipped frame is simply absent from both the PSNR average and the VMAF average. It is very unevenly distributed: OpenH264 dropped at least one frame in 120 of its 480 runs (25.0%), against 18 for VP8, 13 for VP9 and 22 for AV1, concentrated on the two low-bitrate rungs. The drops are the opposite failure from the undershoot above: they cluster at high QP, 40–44% of runs with a mean QP of 24 or more against 9% of runs at the QP 12 clamp. In the per-frame trace of the worst run every one of its 18 drops directly follows a burst frame of 3–13× the per-frame budget, against a median frame of 0.15×, so the encoder underspends, is caught out by a scene change, overshoots hard and then skips a frame to pay the leaky bucket back. Some part of what OpenH264 wins on quality it buys by not sending frames, and no number on this page subtracts that. The
frames_decodedcolumn in the VMAF dataset records it per run. - The upscaled VMAF depends on the scaler. Bicubic is the convention, but a browser compositor may use something else, so the absolute “on a 1080p screen” values move with that choice. The ordering across rungs does not.
Reproducing this
Everything on this page comes from three CSV files, and every one of them is regenerable from the commands below. No step depends on state held anywhere else.
Environment
- Machine
- A single x86-64 Linux desktop, unchanged across every pass. Every run is pinned to
--num_cores=2, so the thread count of the host only affects how many runs proceed at once, not what any one run measures. Absolute timings, and even the ratios between bars, may change on another machine because the codecs use different optimizations and scale differently with the hardware. - libWebRTC
- Built from the tree at
c9baebb35d. The binary isvideo_codec_perf_tests; the quality, VMAF and timing passes all use the same one. - args.gn
is_debug = false,rtc_use_h264 = true,ffmpeg_branding = "Chrome",proprietary_codecs = true,symbol_level = 1.- External
- libvmaf
f5f3664with its built-in models, so no model file is needed on disk. FFmpeg 6.1.1 is used only to decode the source MP4s and to perform the bicubic upscale.
|
1 2 3 |
gn gen out/Default --args='is_debug=false rtc_use_h264=true ffmpeg_branding="Chrome" proprietary_codecs=true symbol_level=1' third_party/siso/cipd/siso ninja -C out/Default video_codec_perf_tests |
autoninja and ninja.py both fail against a Siso-generated state file in this checkout; calling siso ninja directly is the way through.
The dataset
The clip list ships with the dataset repository, and the clips themselves come from a public Azure blob. Only the three landscape scenarios are used, giving the 120 clips; each is decoded to raw I420 once and every run for that clip reads the same file.
|
1 2 3 4 |
git clone --depth 1 https://github.com/microsoft/VCD.git vcd grep -E '/(th|th-ob|th-bb)/' vcd/download/mp4_list.txt # 120 clips curl -O https://vcdpublic.blob.core.windows.net/vcd1/${blob} ffmpeg -i clip.mp4 -pix_fmt yuv420p -f rawvideo src.yuv |
The three passes
Each script is unattended, resumable, and streams results as they land, so an interrupted run loses at most the work in flight. All three live in the repository root.
- vcd_run.py
- The quality pass: 4 codecs × 4 resolutions × 120 clips. Produces
vcd-psnr-results.csv, 1,920 rows. - vcd_vmaf_full.py
- The VMAF pass, same grid, adding the y4m dumps and both scoring conventions. Produces
vcd-vmaf-full.csv, 1,920 rows, and re-derives PSNR as a cross-check. - vcd_timing.py
- Timing for all four codecs in one pass so the bars are mutually comparable. Produces
vcd-timing.csv, 1,920 rows.
How the aggregates are defined
Three rules turn those rows into the numbers above, and all three are recomputable from the CSVs alone.
- Rate-matched subset. A clip enters the headline PSNR chart at a given resolution only if all four codecs delivered within ±10% of target there, so the comparison is at equal rate. That is
abs(bitrate_mismatch_pct) ≤ 10for all four, giving n = 93, 96, 71 and 93 clips. The side-by-side PSNR and VMAF panels deliberately skip this and use all 120, because their job is to compare metrics rather than to rank codecs. - Saturated. A run undershooting its target by more than 20% is counted in the “saturated” column: the encoder hit its quality ceiling and could not spend the budget.
- Frame alignment. Decoded frame indices come from the per-frame CSV as
(timestamp_rtp - 90000) / 3000over rows carrying a PSNR value. When that list is shorter than 300, the reference is subset to it before VMAF runs.

Leave a Reply